Pivot
A long table made wide: a row per group and a column per category of a field.
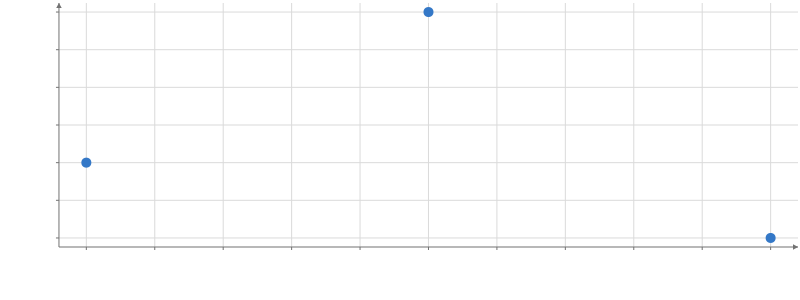
Static preview; loading the interactive plot
import hmplot as hm

data = {
    "shape": ["a", "a", "b", "b", "c", "c"],
    "measure": ["width", "height", "width", "height", "width", "height"],
    "value": [1, 2, 3, 1, 2, 4],
}
with hm.Plot(data=data, height=300, axes2d=True) as plot:
    with hm.Pivot(field="measure", value=hm.sum("value"), by="shape"):
        hm.Points(x="width", y="height")
plot
Usage
Outputs one row per by key and a column per field category (first and second in this excerpt). value is a reduction expression that fills each cell from the group’s rows in that category: value={sum("value")} (Python value=hm.sum("value")), mean("value") or count(). Missing combinations become NaN. Duplicate output names and source-column collisions are errors.
To let the viewer change a setting, read an input in it: by={input("by")} (Python by=hm.input.by), where by is a Select of column names.